Exploring Speculative Decoding in vLLM on AMD GPUs
Speculative decoding can boost vLLM token throughput, but gains vary with drafting method, model family, and workload.
174 candidate events; 59 shortlisted stories; 52 with article text available; 16 selected. Counts describe different stages; clustering, validation and refills can change the shortlist.
Active filters: none. Sort: Ranked.
All 16 stories, in ranked orderSpeculative decoding can boost vLLM token throughput, but gains vary with drafting method, model family, and workload.
Gartner says over 40% of current agentic AI projects will fail by 2028 because of rising costs and unclear business value.
Inherent says its Faraday agent reproduced published scientific findings without prompts, outperforming larger Anthropic and OpenAI models.
The paper argues that omitting human beliefs causes world models to predict wrong actions.
Netflix reports its GenRec model improves recommendation quality while needing far less labeled training data than the legacy system.
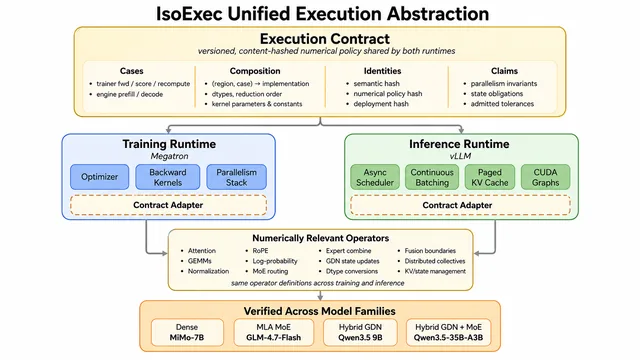
IsoExec enforces identical floating‑point rounding across rollout and training, cutting log‑probability mismatch to below 1e‑6 with modest overhead.
Decoding AI shows that changing only the harness can move a coding agent from 30th to top‑5 performance.
The video explains Claude’s new watermarking process, detailing token sampling, detection, and removal steps.
llm 0.33 updates embed methods to accept per‑call keys and adds template repetition for combined prompts.
Princeton and UC San Diego find skills improve agents mainly via structured workflows, but hit rate drops as libraries grow.
The tutorial builds a NeMo Guardrails pipeline that adds layered safety checks, including deterministic PII redaction and token accounting.
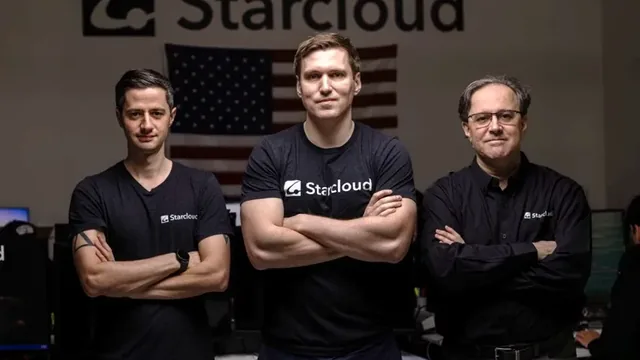
Starcloud raised an additional $250 million to expand orbital data center production and secure launch slots on SpaceX Starship.
Together AI reports GLM‑5.3 matches Claude Fable 5 on accuracy but costs about one‑fifth per rollout.
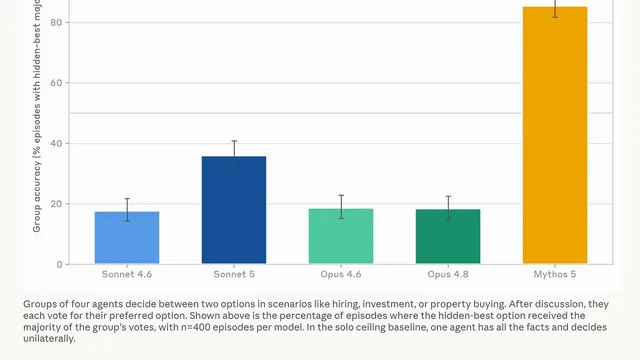
Exponential View notes Anthropic’s experiment shows a single agent often outperforms a group, exposing hidden‑profile bias.
Guideline AI Standards finds most frontier labs lack documented containment plans, with OpenAI scoring highest and Anthropic lowest.
Community discussion notes Anthropic is A/B testing reduced effort levels in Claude Code via a server‑side experiment.
No stories match. Active filters.